 Jason Peterson
Conform is where the edit meets the color pipeline. An edit decision list comes in, and the colorist’s session fills up with the right source clips, in the right order, cut at the right in and out points. When it works, nobody notices. When the metadata is stripped, corrupted or just wrong, it stops working, and the colorist goes hunting for the source by hand.
A teammate was building a system that, when metadata conform couldn’t find a shot, used DINOv2 to show the colorist the most similar shots. It found candidates, but it didn’t align them: no in and out points, no exact frame. I wondered about a different approach, with a different model, that would find the clip and line it up to the frame.
I built that.
BLAST, but for frames
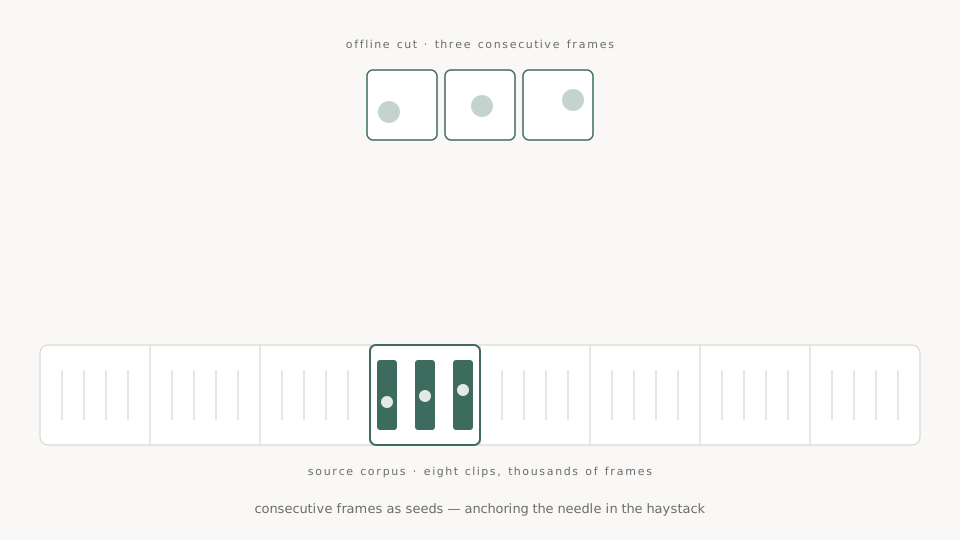
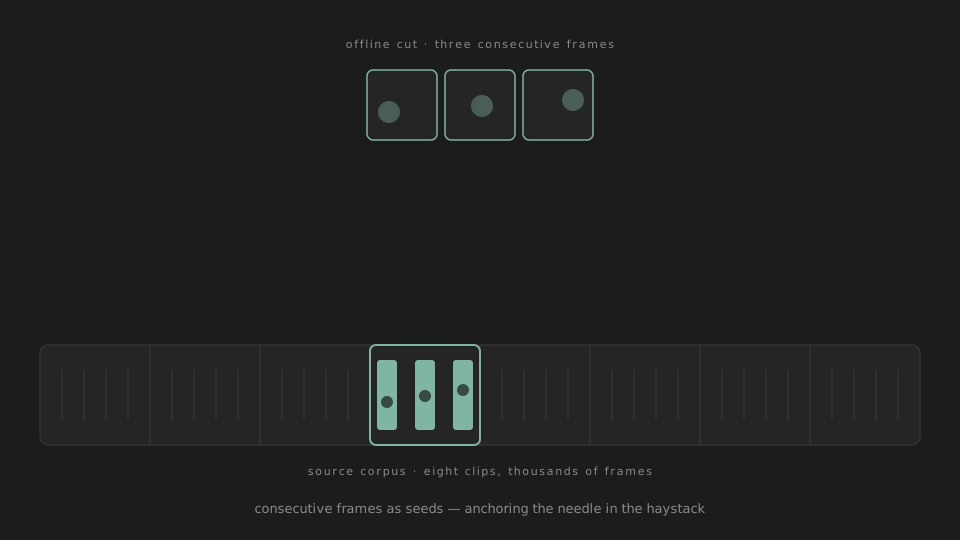
The job is a search. A short piece of footage from the offline cut is the needle. Every camera-original clip in the project is the haystack. Search on a single frame and you’ll drown in lookalikes across takes. Search on two consecutive frames and it gets specific, because the exact change between them (a head turning, a light shifting, a flag of motion) is unlikely to happen the same way anywhere else.
Bioinformatics found DNA in genomes on the same insight. BLAST looks for short matching substrings, k-mers, as seeds, then extends each seed into the context around it. Different domain, same mechanic.
The matcher runs in three stages:
- Seed. An approximate-nearest-neighbor lookup on embeddings of consecutive frame pairs. Whichever source clip and offset collects the most seed hits wins.
- Extend. Smith-Waterman alignment of the offline shot against that clip’s frame range, to lock the in and out points.
- Refine. A last sweep of a few frames either side, keeping the offset with the highest mean cosine similarity per frame.
Each stage narrows it down. The seed finds the clip, the extend finds the region, and the refine finds the frame.
Why SSCD, not DINOv2
My teammate’s system used DINOv2, a strong general-purpose vision model. For mine I used SSCD, Meta’s copy-detection embeddings. SSCD was trained for content moderation, to match an image after heavy crops, resolution changes, color shifts and overlays. That’s what a conform fallback is up against. The offline cut has been re-encoded, transcoded, graded and sometimes letterboxed. The source is camera original. Whatever shrugs off that range of changes wins.
I ran the two head to head on a clip pushed through seven kinds of damage: letterbox, crop, double LUT, heavy compression, low-res upscale, burn-in and display transform. DINOv2 separated matches from non-matches more cleanly on the easier cases. SSCD held up better on the messy ones, and it’s smaller, faster and MIT licensed. For a fallback, that was the better fit.
Ground truth by construction
The hard part of building something like this isn’t the matcher. It’s knowing whether the matcher works. Real EDLs come with retimes, transcodes and human error baked in, so the right answer is muddy.
So I built my own test. Pick a random source clip and frame range, push it through one of the seven kinds of damage, then try to match it back. The right answer is known, because I made the test from it. No trusting the EDL, no metadata drift.
I ran 100 trials per kind of damage, 700 in all, and scored whether the matcher found the right clip and how close it landed to the right frame.
Results
On a real EDL of 207 events, 354 source clips and about eleven hours of dailies (a 30:1 shoot ratio), the matcher found the correct clip every time. It was frame accurate on 88% of events, and within one frame on 92%. The EDL’s four retimes were out of scope for this version.
On the 700 synthetic trials, it found the correct clip 99% of the time, frame accurate on 91%.
Nearly all of the 8% that land more than a frame off on the real EDL are locked-off shots, mostly static, almost painterly: a landscape, leaves moving in the wind, a framed photo on a wall. Consecutive frames in those barely differ, so there’s no fingerprint to follow, and the matcher can land 50 to 190 frames off. It scores those matches low, so they’re easy to pick out of the report and check by eye.
As with every project like this, real footage turned up a nuance the concept didn’t predict. For those static shots, a cutaway to a landscape or a teapot coming to a boil, I’ve since added a motion comparer that uses old-school FFT to match the faint movement that is there. I haven’t rerun this exact footage since, but I’d expect it to cut that 8% at least in half.
How it runs
The prototype became two small pieces of software, both meant to be easy to deploy.
fl-enrich is a terminal app that vectorizes the source and offline footage. It runs SSCD through a Swift binary that spreads CoreML across the Neural Engine and GPU of an Apple Silicon Mac, with six worker processes feeding an FFmpeg fallback for codecs AVAssetReader can’t decode. On an M3 Ultra it does about 420 frames per second across 25 parallel workers, with decoding pipelined alongside inference.
The embeddings land in a LanceDB directory, keyed by each clip’s basename. It’s just a directory on disk: no service to run, no system dependency, only a pip install. The whole thing can ship to wherever the colorist is grading.
A FLAPI package inside Baselight does the matching. The colorist runs metadata conform as usual and aims for a clean 100%. Anything that fails gets marked. Scene → Visual Conform Fix → Match walks each missing shot, runs the three stages against LanceDB, and inserts the source clip it found below the gap. Each insert is color-coded by verdict: green for frame accurate, yellow for a partial overlap, orange for the right clip in the wrong place, red for the wrong clip.
A separate Visualize Match step opens an HTML report in the browser. Each card shows the inserted shot’s center frame, the verdict, how much it overlaps the right answer, and where the seeds hit. It’s quicker to scan than stepping through marks on the timeline.
What I learned
One frame is hopeless. A few in a row are a fingerprint. The whole BLAST idea hangs on this. A single frame has too many lookalikes across takes for the search to settle. Two or three together are specific.
Vectorizing up front pays for itself. Once the source is vectorized, matching takes under a second per missing shot, even against about a million pair embeddings at a 30:1 shoot ratio. The expensive part happens once, in the background, away from the colorist’s session.
The right embedding isn’t always the strongest one. SSCD beat DINOv2 here because what it was trained to ignore (compression, recoloring, overlays) is exactly what separates the offline from the source.
If you can build your test data, build it. When you make the test, you know the answer. Every kind of damage becomes a fresh test set on demand, with none of the “is this label even right?” doubt that comes with hand-labeled data.
For now it’s a demo on a private machine. Not production code, not even close. But the matcher, end to end, works.